Writing
Things that broke, and what they cost.
Notes from running production. Mostly about the gaps between layers, because that is where the expensive problems live.
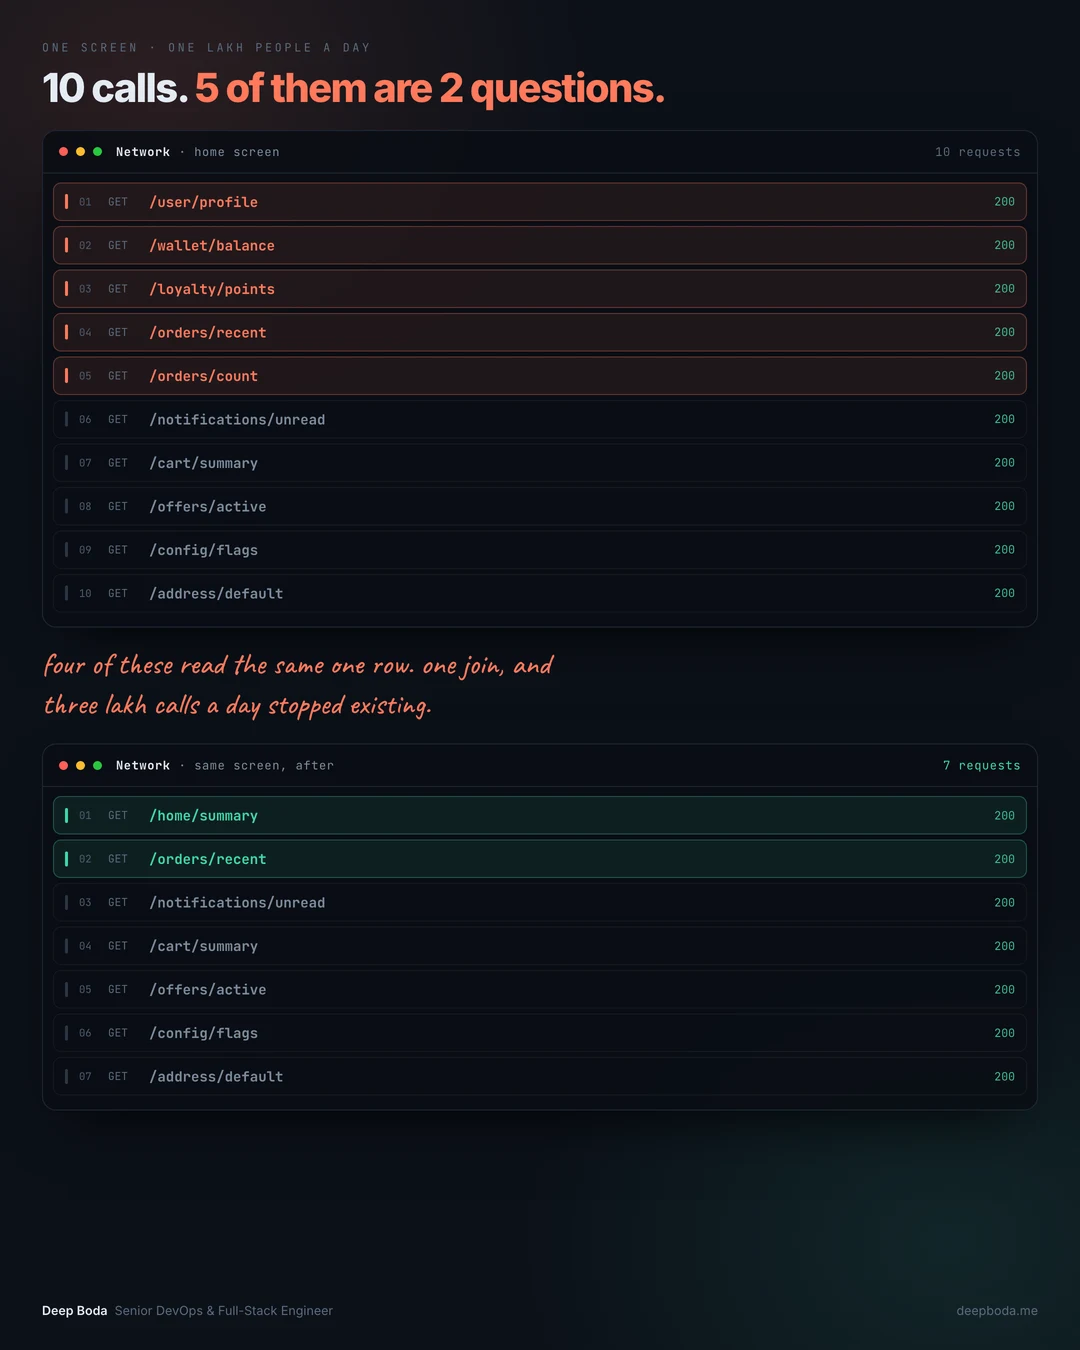
Ten API calls. Three of them were the same question.
The ask was more servers. I spent a day counting instead. One screen, ten calls, one lakh opens a day, and three lakh requests that never needed to exist.
 6 min
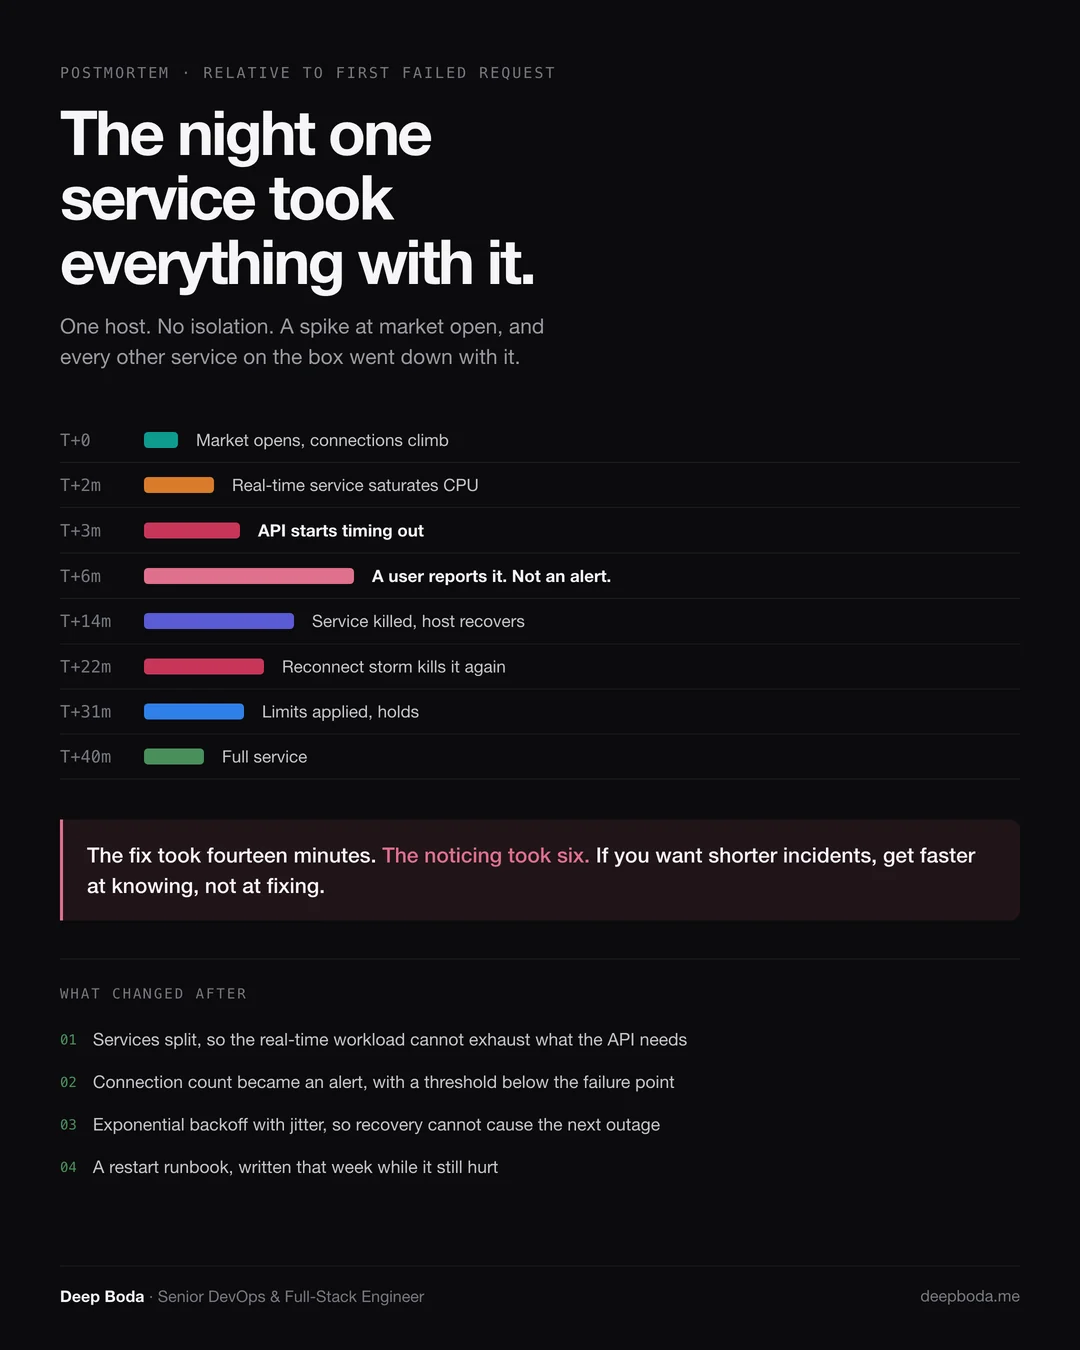
The night one service took everything with it
A real postmortem, written the way I write them internally. One host, no isolation, a spike at market open, and every other service on the box went down with it.
PostmortemSRE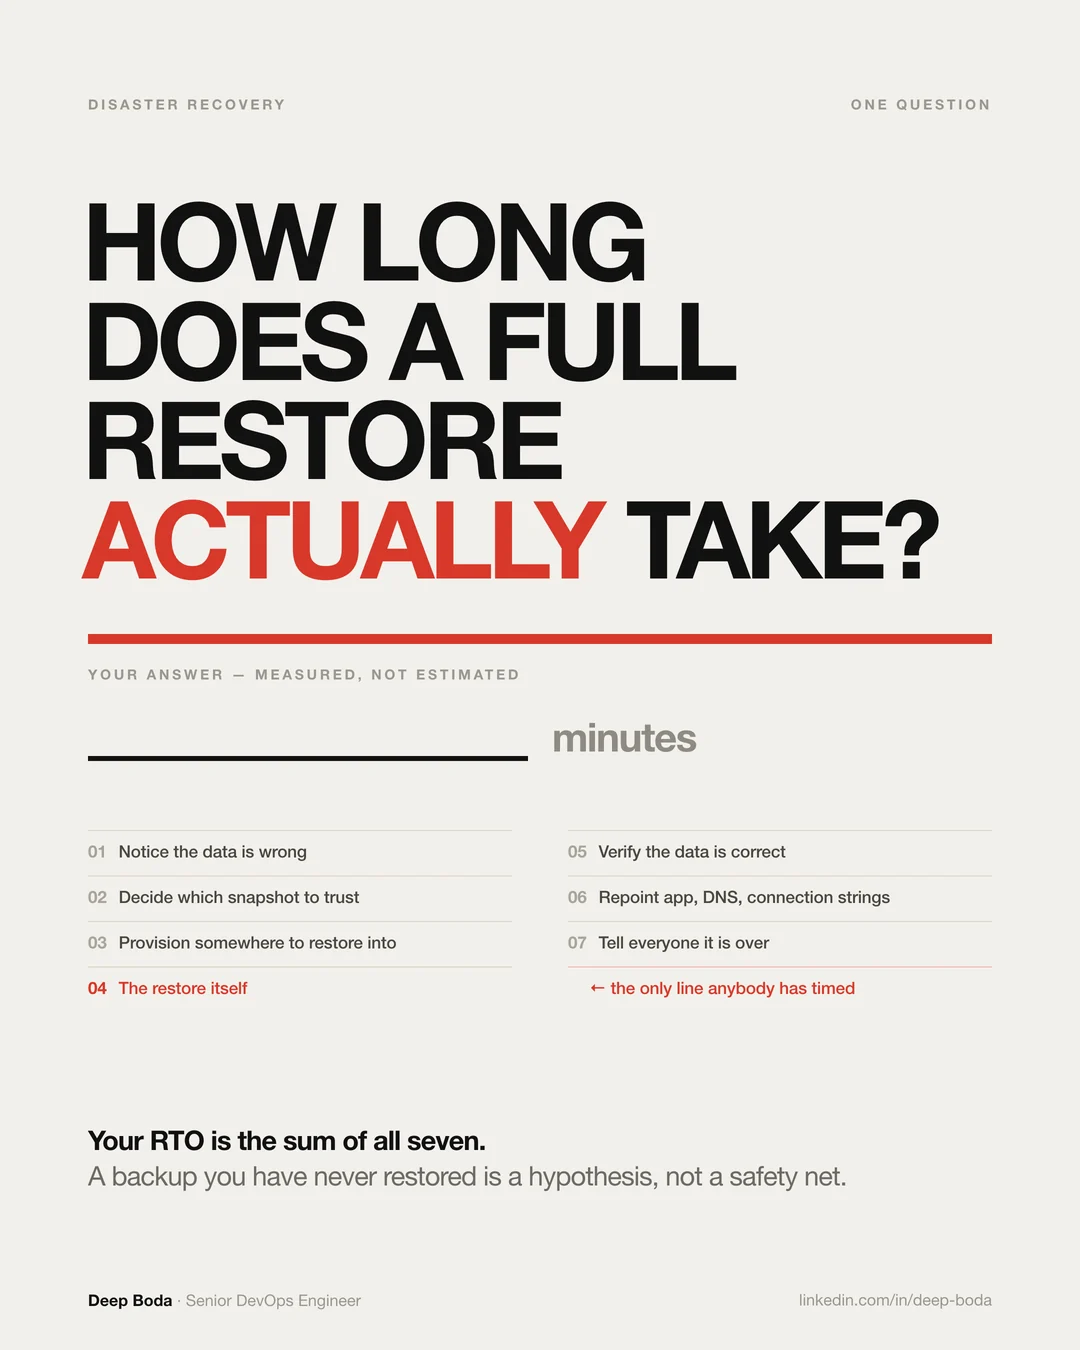 4 min
You don't have backups. You have files.
Everyone asks whether you have backups. Almost nobody asks how long a restore takes, and only one of those questions matters at 3 AM.
ReliabilityDisaster Recovery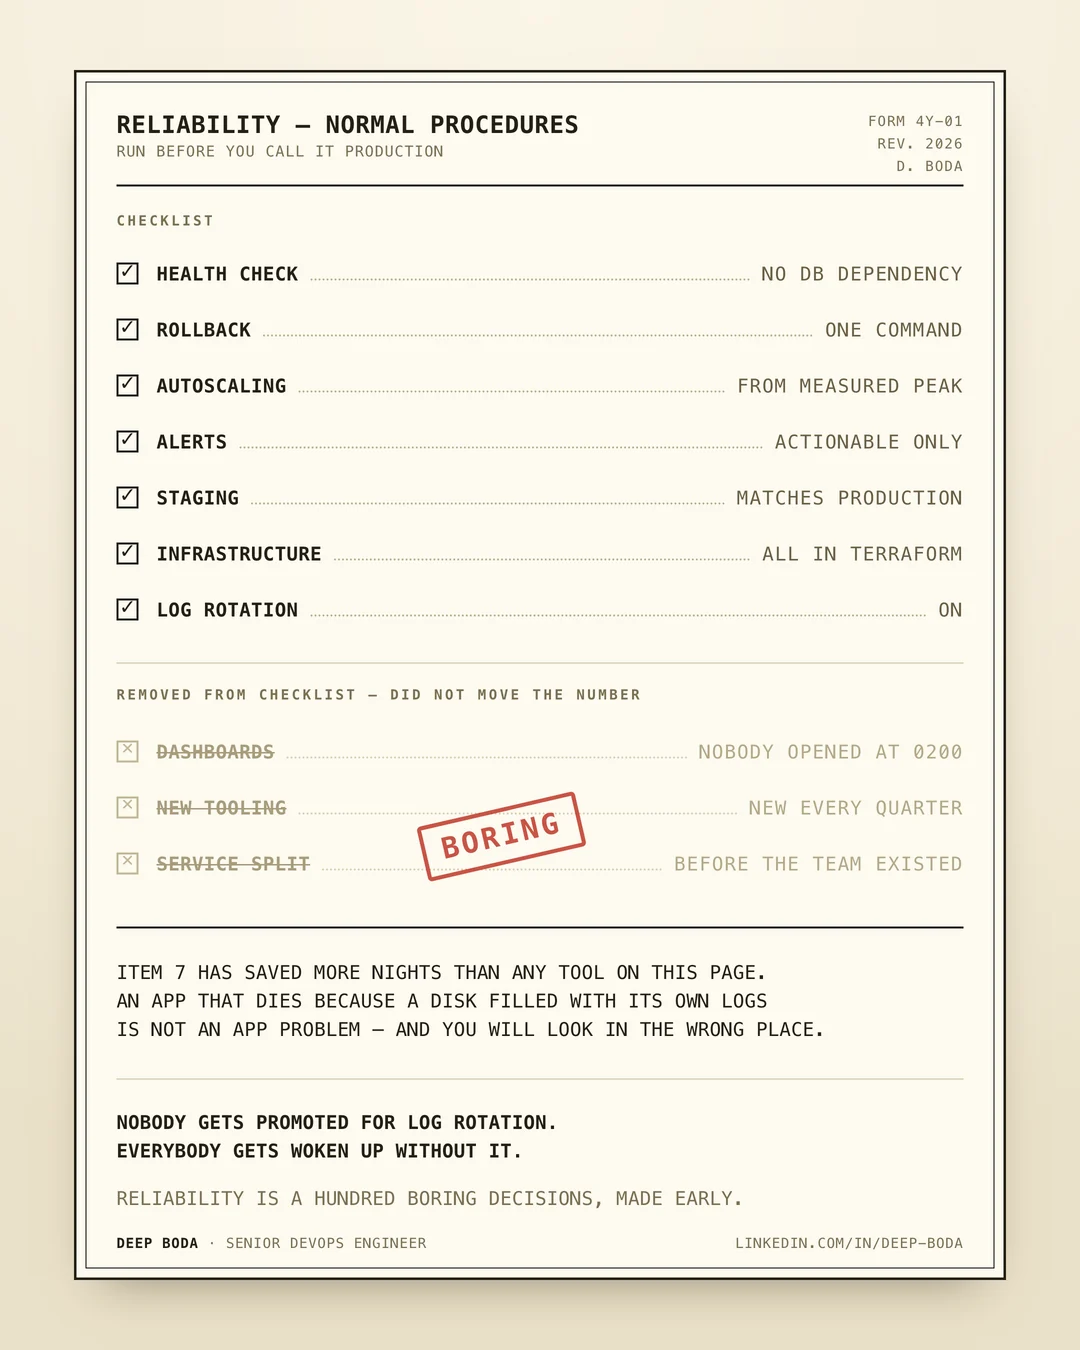 4 min
None of it was exciting
Four years of infrastructure work. The things that genuinely moved reliability were embarrassingly boring, and the exciting ones did nothing.
ReliabilitySRE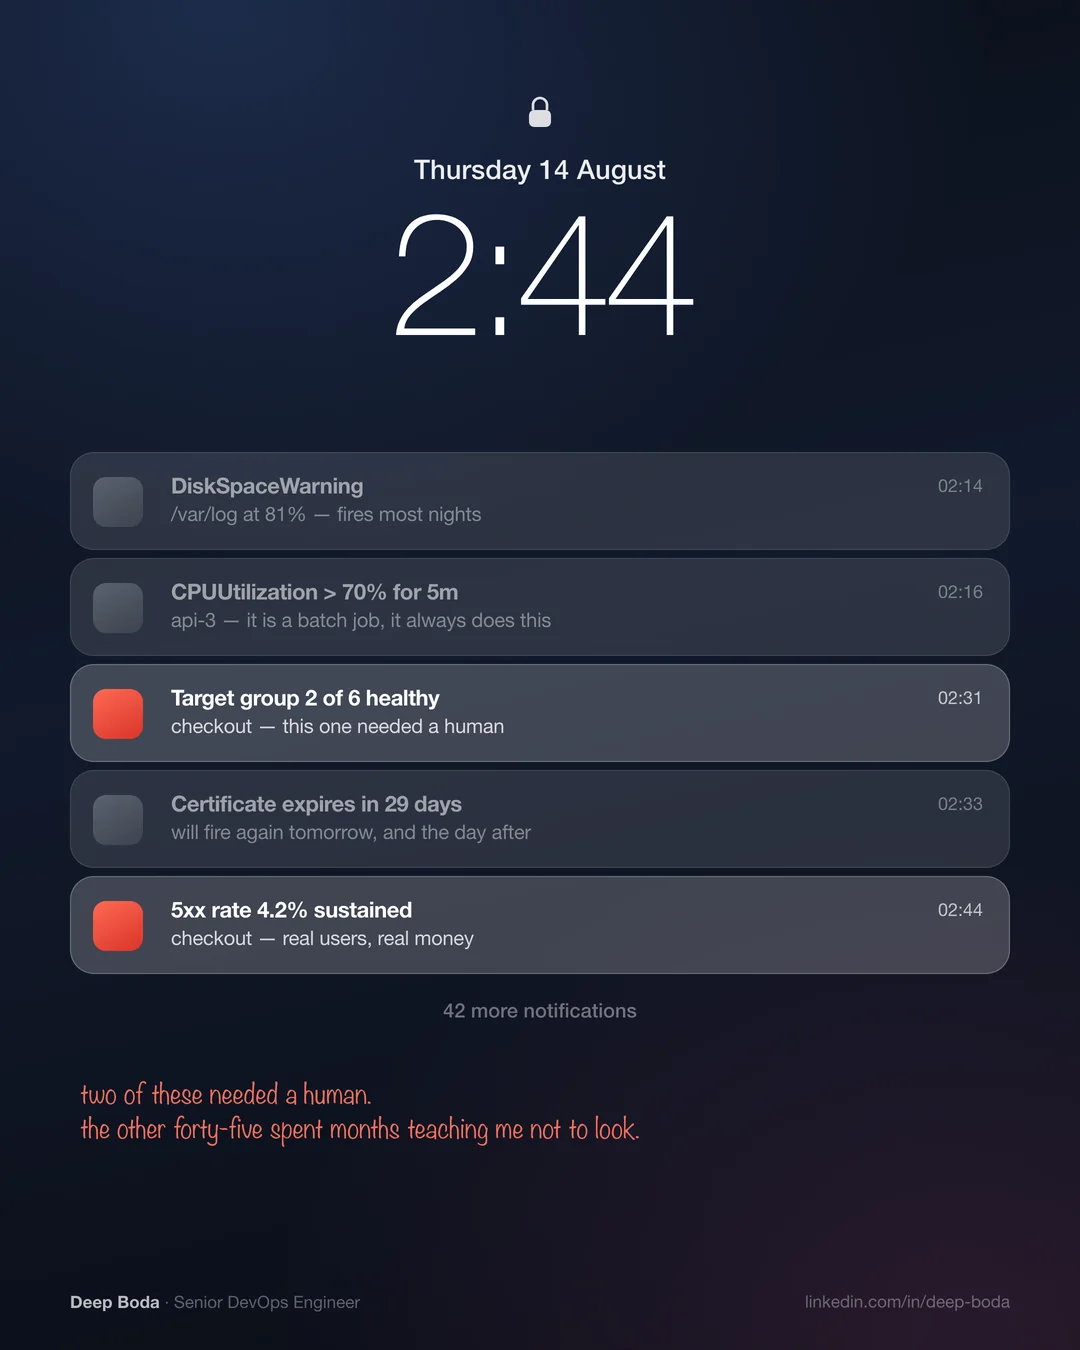 4 min
47 alerts. Two mattered.
I muted a production alert last month and it was the right call. An alert that fires every night and never needs action is not monitoring.
SREOn-call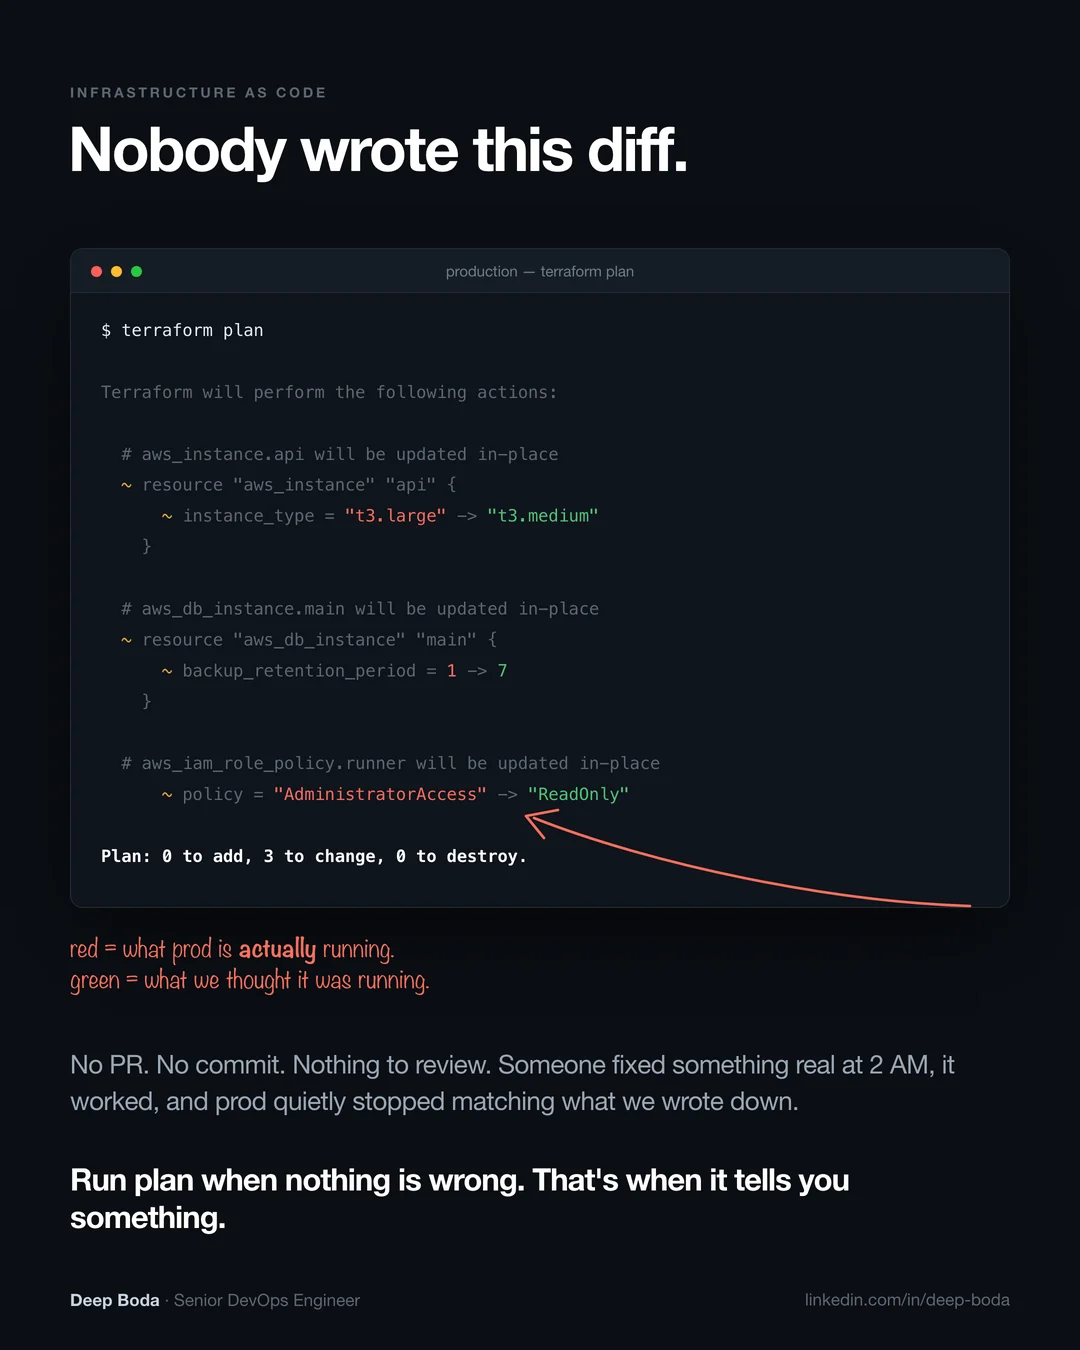 5 min
Nobody wrote this diff
I ran terraform plan against production when nothing was wrong. Three things came back changed, and one of them was mine.
TerraformAWS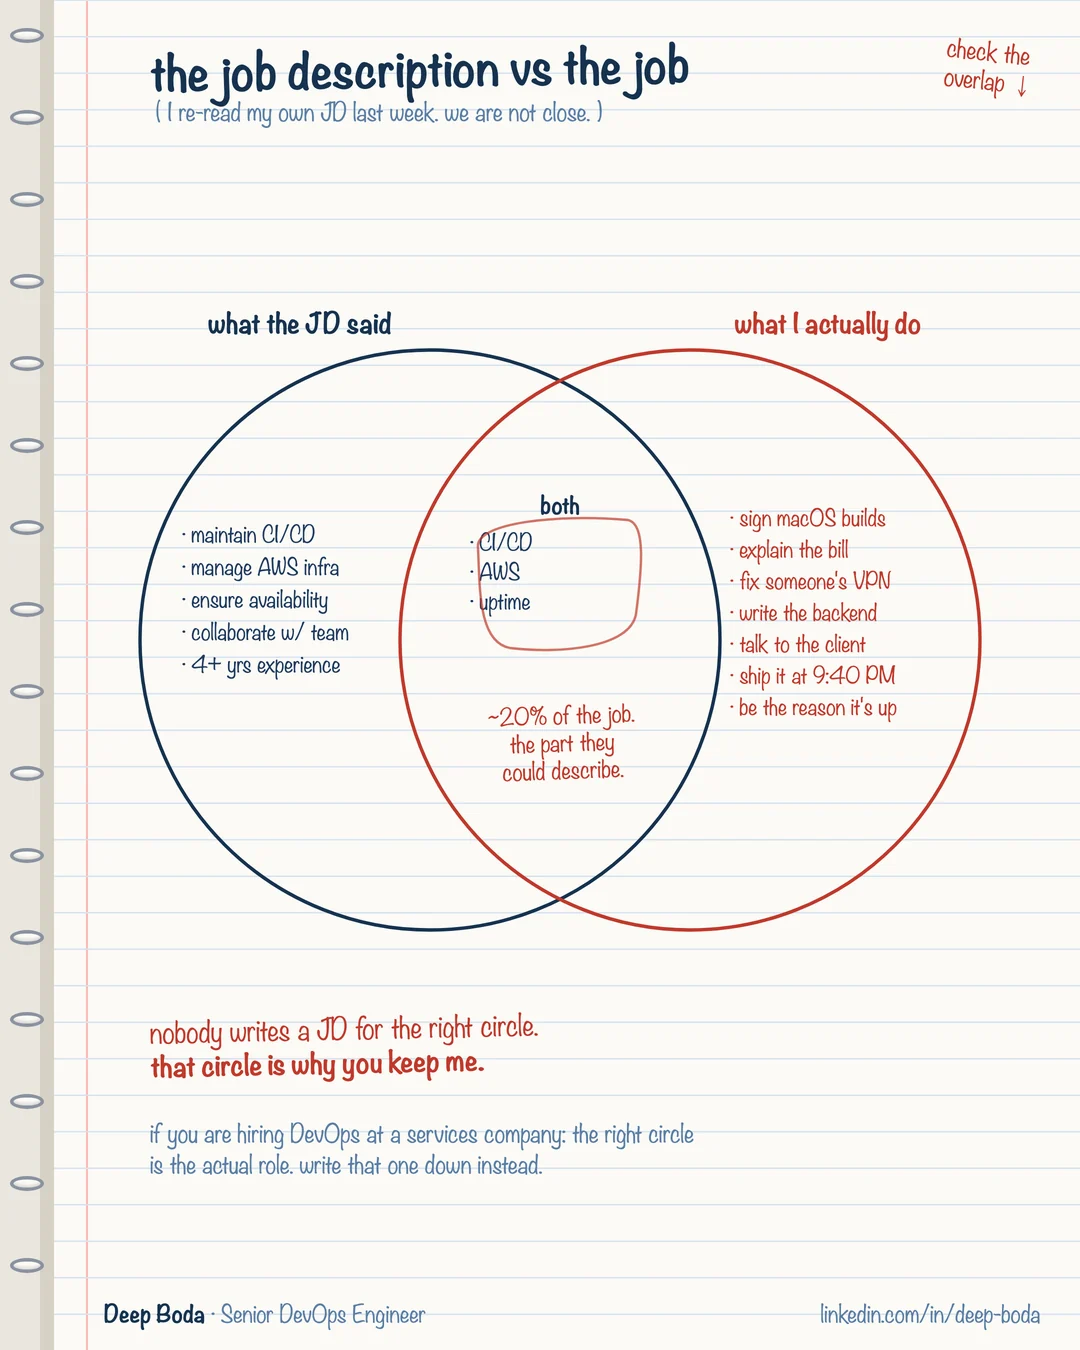 4 min
The job description versus the job
I re-read my own job description last week. It describes about 20% of what I actually do. Nobody writes a JD for the other circle.
HiringDevOps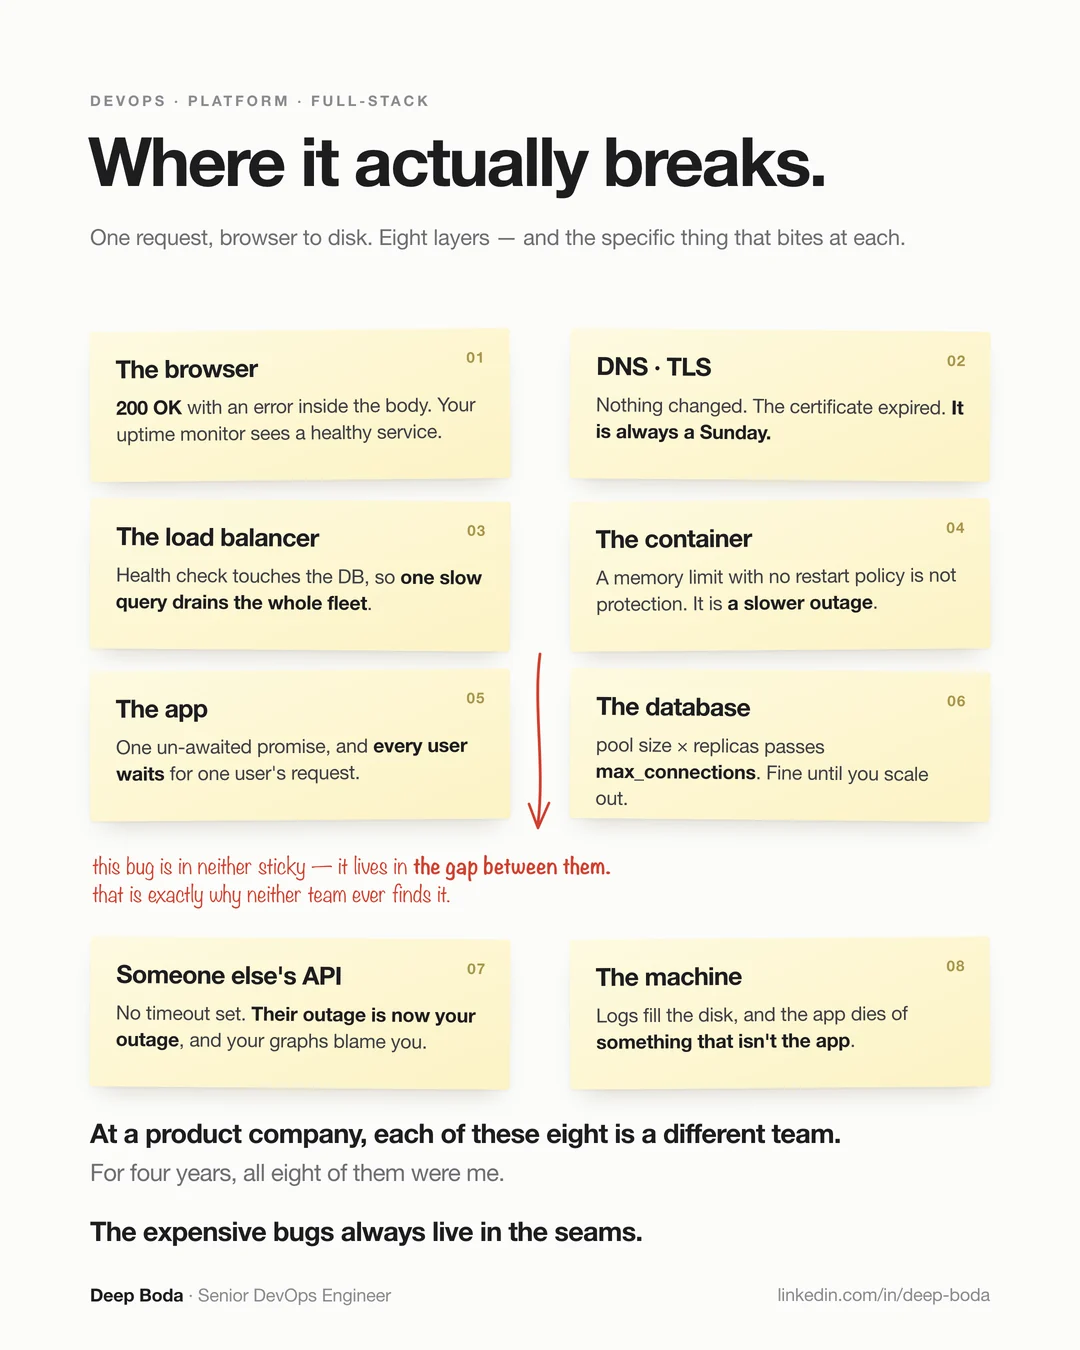 6 min
Where it actually breaks
One request, browser to disk. Eight layers, and the specific thing that bites at each one. The expensive bugs live in the seams between them.
DevOpsPlatform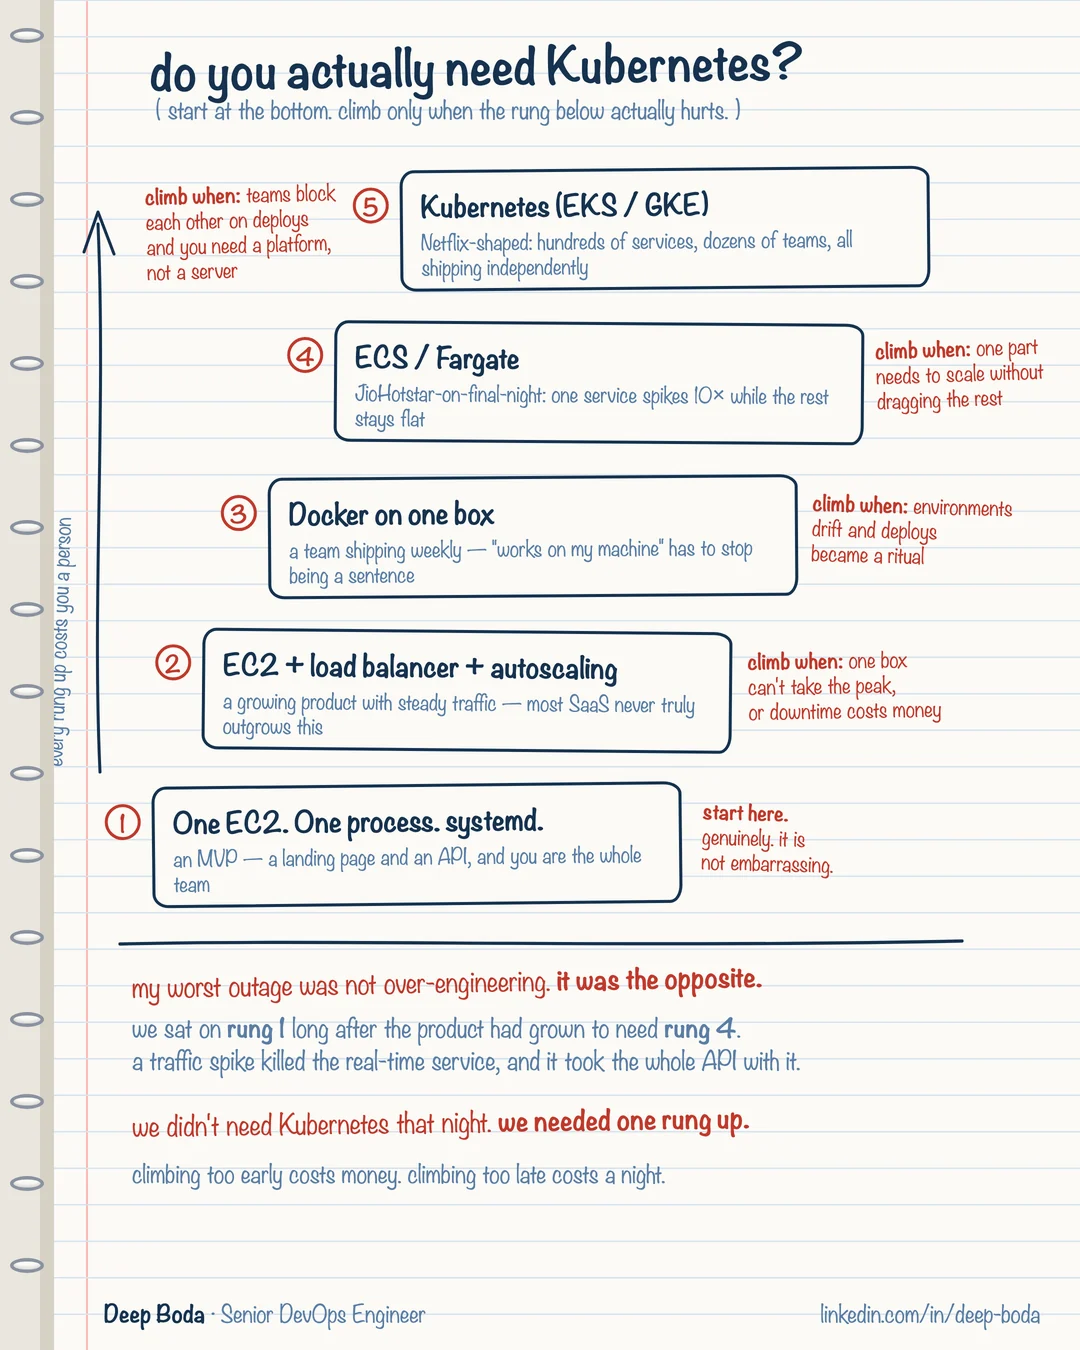 5 min
Do you actually need Kubernetes?
Five rungs, simplest at the bottom. I run all of them in production right now. Climbing too early costs money, climbing too late costs a night.
KubernetesAWS